> For the complete documentation index, see [llms.txt](https://ykkim.gitbook.io/dlip/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://ykkim.gitbook.io/dlip/programming/pytorch/neural-networks.md).
# Simple ConvNet
## Train a simple Convnet
Neural networks can be constructed using the `torch.nn` package
An `nn.Module` contains layers, and a method `forward(input)`that returns the `output`.
A typical training procedure for a neural network is as follows:
* Define the neural network that has some learnable parameters (or weights)
* Iterate over a dataset of inputs
* Process input through the network
* Compute the loss (how far is the output from being correct)
* Propagate gradients back into the network’s parameters
* Update the weights of the network, typically using a simple update rule: `weight = weight - learning_rate * gradient`
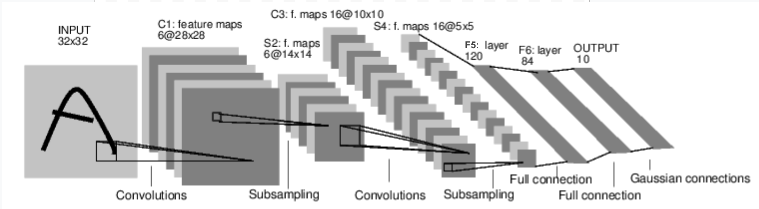
input -> conv2d -> relu -> maxpool2d -> conv2d -> relu -> maxpool2d -> view -> linear -> relu -> linear -> relu -> linear -> MSELoss -> loss
## Define the network
Let’s define this network:
> tensor.view(-1,n), Returns a new tensor with the same data as the self tensor but of a different shape. the size -1 is inferred from other dimensions
```python
import torch
import torch.nn as nn
import torch.nn.functional as F
class Net(nn.Module):
def __init__(self):
super(Net, self).__init__()
# input ch, output ch, convolution
# 1 input image channel, 6 output channels, 3x3 square convolution
# kernel
self.conv1 = nn.Conv2d(1, 6, 3)
self.conv2 = nn.Conv2d(6, 16, 3)
# an affine operation: y = Wx + b
self.fc1 = nn.Linear(16 * 6 * 6, 120) # 6*6 from image dimension
self.fc2 = nn.Linear(120, 84)
self.fc3 = nn.Linear(84, 10)
def forward(self, x):
# Max pooling over a (2, 2) window
x = F.max_pool2d(F.relu(self.conv1(x)), (2, 2))
# If the size is a square you can only specify a single number
x = F.max_pool2d(F.relu(self.conv2(x)), 2)
x = x.view(-1, self.num_flat_features(x))
x = F.relu(self.fc1(x))
x = F.relu(self.fc2(x))
x = self.fc3(x)
return x
def num_flat_features(self, x):
size = x.size()[1:] # all dimensions except the batch dimension
num_features = 1
for s in size:
num_features *= s
return num_features
net = Net()
print(net)
```
## Inputs
`torch.nn` only supports mini-batches. The entire `torch.nn` package only supports inputs that are a mini-batch of samples, and not a single sample. For example, `nn.Conv2d` will take in a 4D Tensor of `nSamples x nChannels x Height x Width`.
If you have a single sample, just use `input.unsqueeze(0)` to add a fake batch dimension.
```python
# Let’s try a random 32x32 input. Note: expected input size of this net (LeNet) is 32x32.
input = torch.randn(1, 1, 32, 32)
out = net(input)
print(out)
# Zero the gradient buffers of all parameters and backprops with random gradients
net.zero_grad()
out.backward(torch.randn(1, 10))
```
## Datasets (MNIST)
`torchvision.datasets.MNIST(root, train=True, transform=None, target_transform=None, download=False)`
* **root** (*string*) – Root directory of dataset where `MNIST/processed/training.pt` and `MNIST/processed/test.pt` exist.
```python
# a batch_size of 64, size 1000 for testing
# mean 0.1307, std 0.3081 used for the Normalize()
batch_size_train=64
batch_size_test=64
# transform = transforms.Compose(
# [transforms.ToTensor(),
# transforms.Normalize((0.5, 0.5, 0.5), (0.5, 0.5, 0.5))])
transform = transforms.Compose(
[transforms.ToTensor(),
transforms.Normalize((0.1307,), (0.3081,))])
# Train set
trainset = torchvision.datasets.MNIST(root='./data', train=True, download=True, transform=transform)
trainloader = torch.utils.data.DataLoader(trainset, batch_size=batch_size_train,
shuffle=True, num_workers=2)
# Test set
testset = torchvision.datasets.MNIST(root='./data', train=False, download=True, transform=transform)
testloader = torch.utils.data.DataLoader(testset, batch_size=batch_size_test,
shuffle=True, num_workers=2)
```
## Loss Function
A loss function takes the (output, target) pair of inputs. There are several different loss functions \`\`
```python
output = net(input)
target = torch.randn(10) # a dummy target, for example
target = target.view(1, -1) # make it the same shape as output
criterion = nn.MSELoss()
loss = criterion(output, target)
print(loss)
```
## Update the weights(Optimization)
various different update rules such as SGD, Nesterov-SGD, Adam, RMSProp, etc.
```python
import torch.optim as optim
# create your optimizer
optimizer = optim.SGD(net.parameters(), lr=0.01)
# in your training loop:
optimizer.zero_grad() # zero the gradient buffers
output = net(input)
loss = criterion(output, target)
loss.backward()
optimizer.step() # Does the update
```